Training defined the first generation of AI infrastructure. Inference will define the next—and it requires a fundamentally different architecture.
As AI transitions from training massive models to serving trillions of daily inference requests, compute is fragmenting across hyperscalers, NeoClouds, sovereign clouds, telcos, and edge locations. Today, inference accounts for over 80% of total AI compute costs, with enterprises wasting up to 40% of their budgets on over-provisioned GPUs, idle capacity, and suboptimal routing.
At Atlaris, we are defining a new infrastructure category to meet this challenge. Atlaris is a software-defined Intelligence Delivery Network built specifically to collapse the cost of enterprise inference.
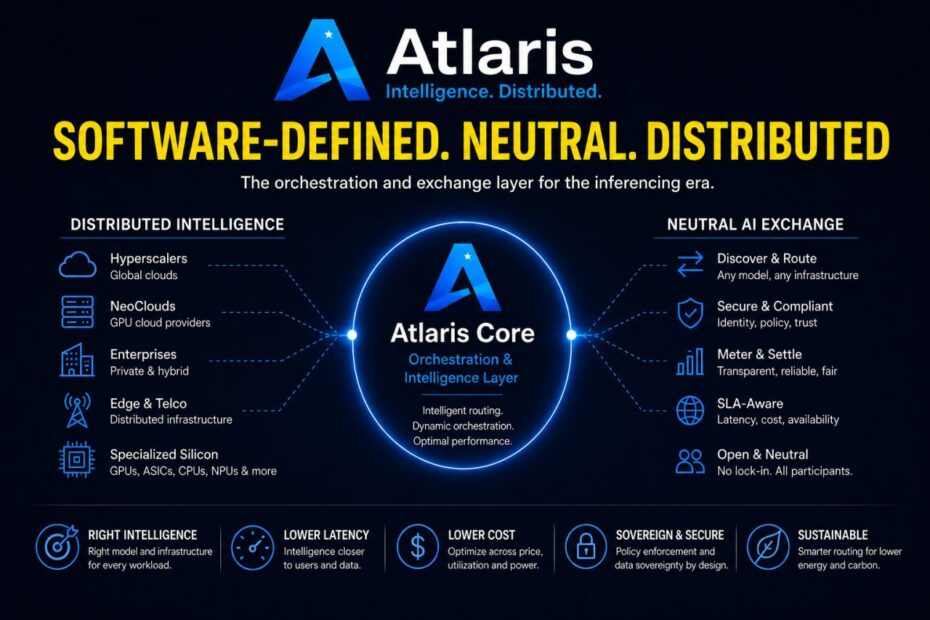
Atlaris dynamically matches every workload with the optimal model, accelerator, and location through:
(1) Distributed Intelligence
Not every request needs an H100running in a centralized datacenter. Routing every prompt to a massive cloud campus is the equivalent of using a freight train to deliver a postcard.
Atlaris brings intelligence where it is needed:
- Heavy workloads run on centralized clusters.
- Latency-sensitive inference executes at regional nodes, slashing round-trip time by up to 70%.
- Specialized tasks route to task-specific silicon, driving down per-token costs by 3–5x.
(2) Software-Defined Orchestration
Atlaris makes heterogeneous compute entirely programmable. In milliseconds, an incoming inference request is evaluated and routed based on:
- Latency constraints
- Real-time GPU availability & memory headroom
- Data locality & residency compliance
- Power economics & dynamic pricing
The question is no longer “Which cloud provider should we lock ourselves into?” It becomes “Where should this specific token run right now for the lowest cost and lowest latency?”
(3) A Neutral AI Exchange
This is the ultimate economic unlock. The inference economy won’t be won by a single walled garden; it will be an open, liquid market.
Atlaris provides a neutral exchange connecting enterprise demand with idle compute across NeoClouds, telcos, and private datacenters—turning isolated capacity into a global fabric.
The Next Infrastructure Frontier
Atlaris is not another GPU cloud. It is not another datacenter buildout. It is not another wrapped API. We are building the Intelligence Delivery Network—the distributed orchestration and exchange engine behind the inference economy.
The Bottom Line:
The first era of AI was about accumulating raw compute. The next era is about making all of the world’s compute behave like one intelligent network—and radically driving the cost of inference toward zero.
That is our mission at Atlaris.