For years, networking was just about connecting GPUs inside a single training cluster. Distributed inference changes the game entirely.
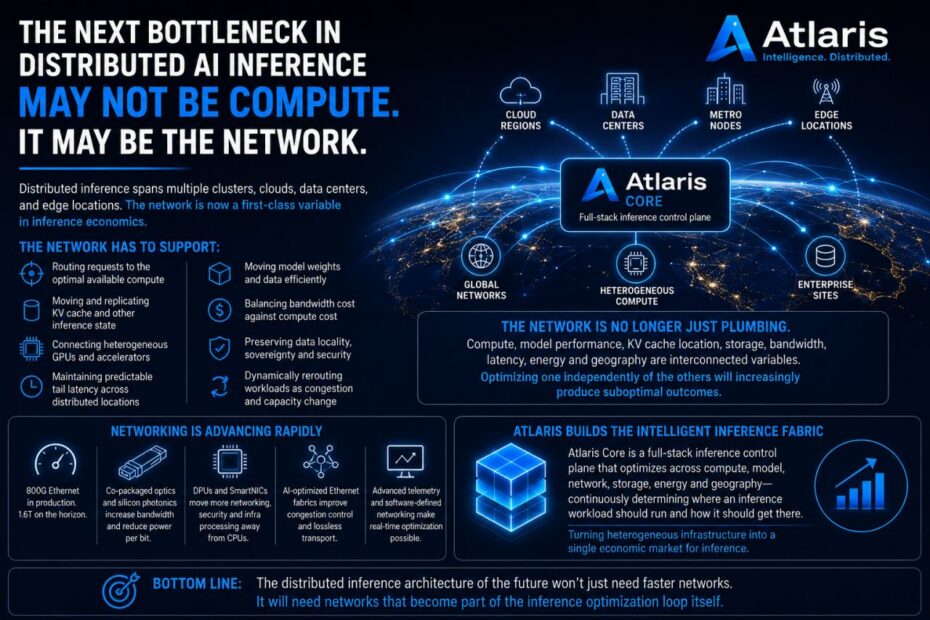
When workloads span 10+ data centers, metro nodes, and edge locations, the core optimization question shifts. It’s no longer just: How fast can GPUs talk to each other? It becomes: How intelligently can workloads, data, and state move across a distributed fabric?
That shift makes networking a primary driver of inference economics.
Consider what the network now has to handle:
- KV-cache mobility: Moving gigabytes of state across clusters with sub-50ms tail latency.
- Dynamic routing: Directing requests across heterogeneous GPU pools (H100s, B200s, L40s) based on real-time capacity.
- Cost balancing: Trading off $0.02/GB egress fees against idle compute costs.
- Locality & sovereignty: Keeping data compliant without sacrificing performance.
Hardware is accelerating fast to meet this demand:
- 800G Ethernet is in production; 1.6T is on the immediate horizon.
- SmartNICs & DPUs are offloading up to 20–30% of host CPU overhead.
- Co-packaged optics (CPO) aim to cut optical interconnect power by >30% per bit.
But the true architectural shift isn’t just about faster pipes. The network can no longer be treated as passive plumbing underneath the AI stack. Compute price, accelerator type, KV-cache location, latency, bandwidth, energy, and geography are deeply interconnected. Optimizing them in isolation guarantees suboptimal performance and inflated costs.
This is exactly what we’re tackling at Atlaris.
Atlaris Core is a full-stack inference control plane. It treats compute, model, network, storage, energy, and geography as a unified equation—continuously calculating where a workload should run and how state should travel to get there.
The Bottom Line:
The goal is no longer just connecting distributed GPUs. It’s creating an intelligent fabric that turns fragmented infrastructure into a single, efficient market for AI inference. The future of distributed inference doesn’t just need faster networks—it needs networks built directly into the optimization loop of the Inference Economy.
#AI #AIInfrastructure #Inference #Networking #DistributedAI #DataCenters #EnterpriseAI